SerSanInside SphereNodeLive at spherenode.com
Sphere AI
SphereNode's bilingual RAG mentor, grounded only in the proprietary curriculum and measured on a 161-question evaluation set.
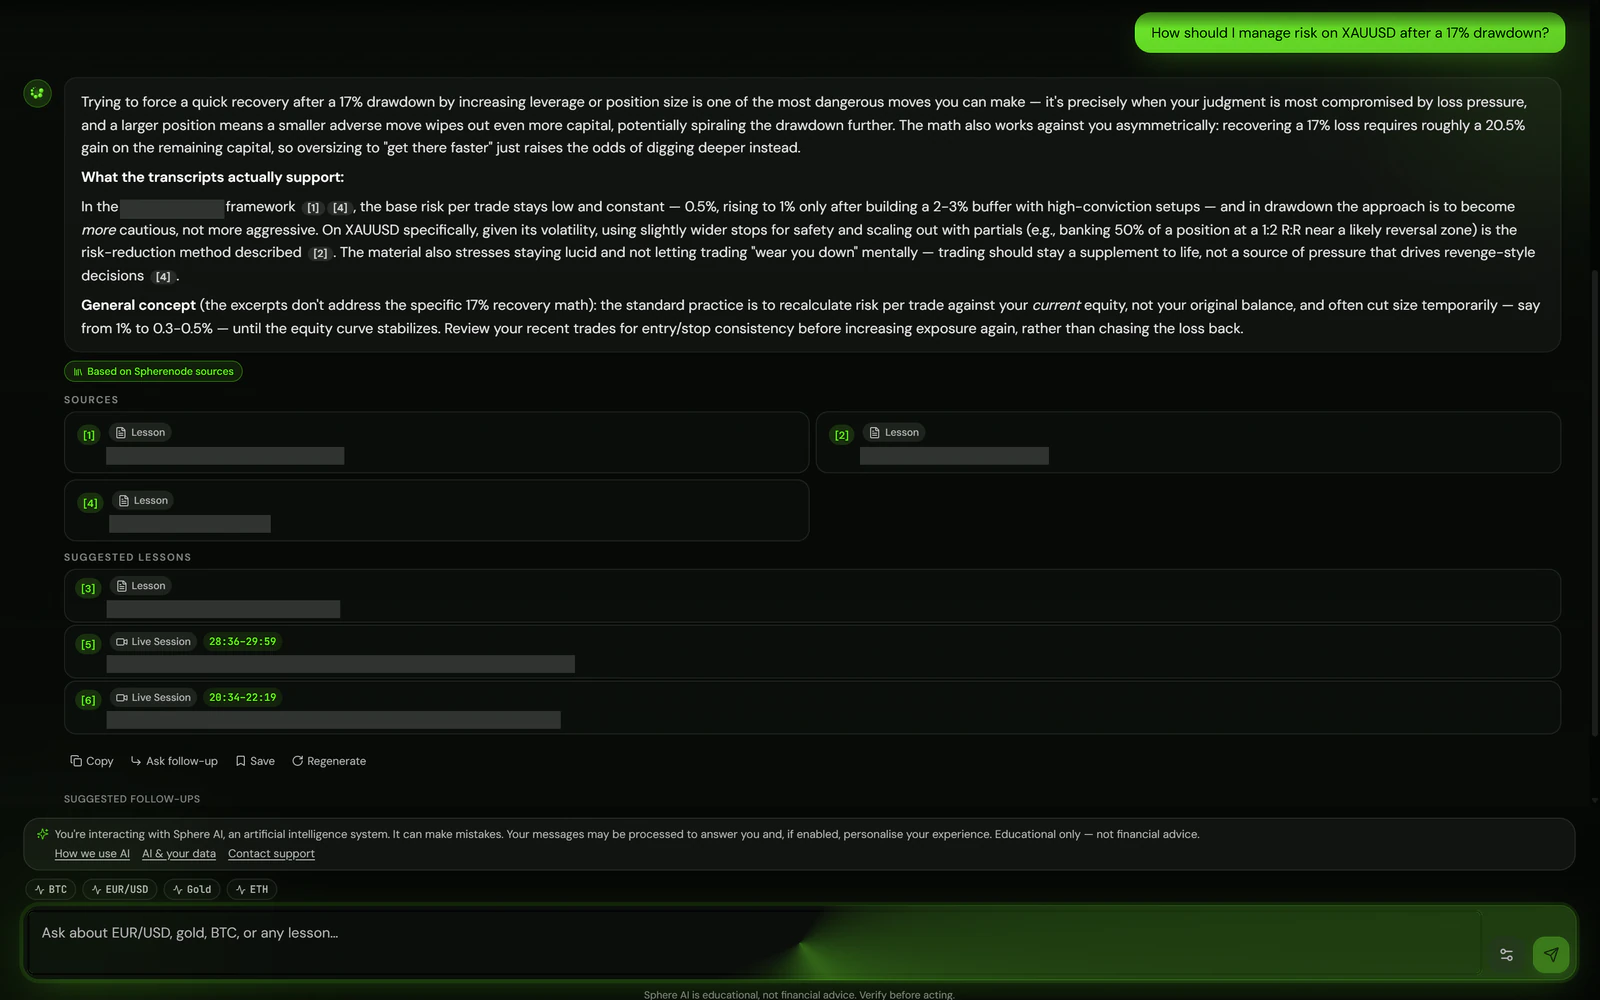
01 What it is
It asksbefore it guesses
Sphere AI is the bilingual (IT/EN) RAG mentor inside SphereNode. It answers only from the platform's proprietary curriculum: semantic chunking and embeddings in pgvector, tier-aware retrieval with a curated fast path for canonical answers, and a generation layer with an LLM relevance grader on top.
Stack
- RAG
- pgvector
- Embeddings
- Semantic chunking
- LLM relevance grader
- LLM evaluation
- Guardrails
- Supabase
02 The pipeline
Curriculumto answer
Every answer starts from the proprietary curriculum and passes a relevance grader before it reaches the trader.
- 01Proprietary curriculum
- 02Semantic chunking
- 03Embeddings in pgvector
- 04Tier-aware retrievalwith a curated fast path for canonical answers
- 05Generation
- 06LLM relevance grader
Then it
- Answers, with citations
- Asks for clarification
- Refuses
Retrieval and generation From the curriculum to an answer, a question back, or a refusal.
03 Measured
Beforeand after
Every change was measured against the same bilingual evaluation set, with zero locked-content leaks and zero fabricated citations.
161-question bilingual evaluation set · before → after
Answer-policy accuracy
52%to68%
Over-answering on questions to withholdLower is better
56%to16%
Clarification precision
75%to94%
Clarification recall
32%to90%
Unsupported claimsLower is better
1.9%to0.6%
Too small to draw on this scale.
Citation correctness · zero fabricated citations
100%
04 The guardrails
What itwill not do
The guardrails behind the numbers
- 01Asks for clarification instead of guessing.
- 02Refuses questions built on a false premise or asking for unsafe actions.
- 03Requires live evidence before answering anything time-sensitive.
- 04Never lets static FAQ content stand in for current market information.
- 05Reads the Trading Journal only as a consent-gated, owner-only source, personal data excluded by default.
05 The record
- Studio
- SerSanSersan LimitedLondonRemote
- Role
- Designed and built it, as Software & AI Engineer
- Lives in
- SphereNode, at spherenode.com
- Evaluation
- 161 questions, Italian and English
More work
- 01SerSan Agent OSSerSan · multi-agent systemOpen
- 02SphereNodeSerSan · live at spherenode.comOpen
- 03Sphere AISerSan · RAG mentorThis case
- 04Maintech OMASerSan · workshop ERPNext
- 05sersan.ioSerSan · Jun – Sep 2026Open
- 06Domus TuaSerSan · real-estate brand platformOpen
- 07Brand filmSerSan · identity and filmOpen
- 08OblaPersonal project · multi-agent systemOpen
- 09Badante24hALS MCL Civitanova · freelanceOpen
- 10Voice AI AgentDOIT S.r.l · internshipOpen
- 11Supply ChainUniversity of CamerinoOpen